When One AI Isn’t Enough: The Real Story Behind Multiagent Systems and AI-Native Development
Picture this. It’s 2 a.m., and you’re staring at a terminal window watching your AI assistant try to refactor a legacy codebase. It’s doing fine — until it hits a test file, then a config file, then a documentation page. Suddenly it’s confused, contradicting itself, and producing code that passes linting but breaks in production. You’ve hit the ceiling of what a single model can hold in its head at once.
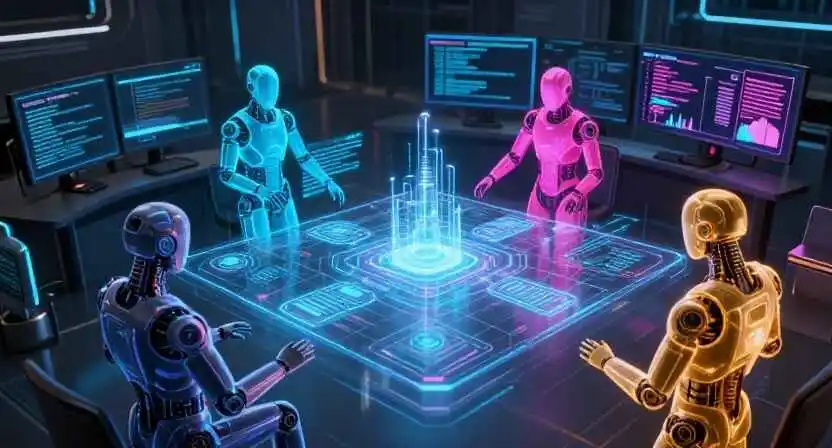
Now imagine a different setup. A “planner” agent maps out the refactor into discrete tasks. A “coder” agent handles implementation. A “reviewer” agent catches bugs. A “tester” agent runs the suite. They argue, iterate, and converge on a solution — without you micromanaging a single prompt.
That’s not science fiction. It’s the emerging reality of multiagent AI systems, and it’s reshaping how we think about building software from the ground up. Welcome to the era of AI-native development — where agents don’t just assist your workflow; they are part of your workflow.
If you’ve been building with LLMs, you’ve probably felt the friction. Single-agent setups are impressive, but they’re also fragile. They lose context. They hallucinate under pressure. They can’t specialize. The industry is quietly moving past that phase, and this post is your field guide to what comes next.
Let’s unpack it properly.
What Multiagent AI Systems Actually Are (No Hype, Just Mechanics)
Before we get into architecture diagrams and framework comparisons, let’s ground this in plain language.
A multiagent AI system is a collection of autonomous AI entities — each with its own role, tools, memory, and objectives — that collaborate (or sometimes compete) to solve problems that would overwhelm a single model.
Think of it like a small startup team, except every team member is an AI. You’ve got the strategist, the researcher, the writer, the editor, the QA person. Each one is good at their job. None of them is good at everything. Together, they ship.
The Core Ingredients
Every multiagent system boils down to a few moving parts:
- Agents: Individual AI units with defined personas, goals, and tool access.
- Memory: Short-term (conversation context) and long-term (vector stores, databases) so agents can learn and recall.
- Tools: APIs, code executors, search engines, file systems — whatever the agent needs to act on the world.
- Orchestration layer: The protocol that decides who speaks when, how information flows, and how conflicts get resolved.
- Shared state: A common ground — a blackboard, a document, a database — where agents coordinate.
Why Bother With Multiple Agents?
Three honest reasons:
- Cognitive load. A single LLM has a finite context window and attention budget. Splitting tasks across agents lets each one focus deeply.
- Specialization. You can tune each agent for its role — different prompts, different models, different tools. A research agent might use a model great at long-context reasoning; a code-gen agent might use one optimized for syntax.
- Checks and balances. Agents can critique each other. This dramatically reduces hallucinations and catches errors a single model would rubber-stamp.
The last point is underrated. When you force an AI to defend its work to another AI, the quality jumps noticeably. It’s adversarial collaboration, and it works.
The Shift to AI-Native Development
Here’s a subtle but important distinction. Most teams today are doing AI-assisted development — they use Copilot, ChatGPT, Claude, and friends to speed up their existing workflow. The workflow itself hasn’t changed. Humans still drive.
AI-native development is different. It means designing your software, your processes, and your team structure around the assumption that AI agents are first-class participants. Not assistants. Participants.
What Changes When You Go Native
| Traditional Dev | AI-Native Dev |
| Humans write most code | Agents generate, humans review and steer |
| One codebase, one team | Modular codebases designed for agent consumption |
| Documentation is an afterthought | Documentation is a first-class artifact agents read and write |
| Testing is periodic | Testing is continuous and often agent-driven |
| Architecture serves humans | Architecture serves humans and agents |
That last row matters more than people realize. If your codebase is a tangled mess of implicit conventions and tribal knowledge, agents will struggle. AI-native development pushes teams toward cleaner abstractions, explicit interfaces, and self-documenting systems — which, coincidentally, makes the codebase better for humans too.
The New Developer Skillset
If you’re a developer in 2026, your job is shifting. You’re less of a line-by-line coder and more of an agent wrangler. Your core skills now include:
- Prompt engineering at scale: Not just writing one good prompt, but designing prompt systems that agents can execute reliably.
- Agent orchestration: Defining workflows, handoffs, and escalation paths between agents.
- Evaluation design: Building rubrics and benchmarks so you know when agents are actually helping.
- Failure-mode thinking: Anticipating where agents will drift, loop, or hallucinate — and building guardrails.
This isn’t about replacing developers. It’s about amplifying the ones who learn to think in systems rather than syntax.
Core Architectures: How Agents Actually Collaborate
There’s no single “right” way to wire up a multiagent system. The architecture you pick depends on your problem. Here are the patterns I see working in production.
Sequential Pipelines
The simplest pattern. Agent A hands off to Agent B, which hands off to Agent C. Think of it like an assembly line.
Good for: Content generation (research → outline → draft → edit), data processing (extract → transform → validate), code generation (spec → implement → test).
Watch out for: Error propagation. If Agent A messes up, everyone downstream inherits the mess. Build in validation checkpoints.
Hierarchical / Supervisor Patterns
A “manager” agent delegates tasks to “worker” agents, reviews their output, and synthesizes a final answer.
Good for: Complex projects with clear subtasks, customer support triage, research synthesis.
Watch out for: The supervisor becomes a bottleneck. If it’s a weak model, the whole system suffers. Consider rotating the supervisor role or using a lightweight router instead of a heavy reasoner.
Debate and Adversarial Patterns
Two or more agents argue opposite positions. A judge agent (or the human) picks the winner.
Good for: Fact-checking, legal analysis, decision-making under uncertainty, catching hallucinations.
Watch out for: Cost. Debate can multiply your token spend 3–5x. Use it where accuracy matters most.
Blackboard / Shared-Memory Patterns
All agents read from and write to a shared workspace. They coordinate asynchronously, picking up tasks as they become available.
Good for: Open-ended research, creative projects, long-running investigations.
Watch out for: Coordination overhead. Without clear protocols, agents step on each other’s work.
Swarm Patterns
Popularized by OpenAI’s Swarm framework, this is a lightweight pattern where agents hand off to each other dynamically based on context — no central supervisor, just peer-to-peer routing.
Good for: Customer support, chatbots with many possible intents, exploratory tasks.
Watch out for: Debugging is harder. Without a clear hierarchy, tracing a failure means following a chain of handoffs.
Picking the Right Pattern
A practical rule of thumb:
- If your task is predictable and linear, use a pipeline.
- If your task has clear subtasks, use a hierarchy.
- If your task needs high accuracy, add debate.
- If your task is open-ended, use a blackboard.
- If your task is dynamic and intent-driven, use a swarm.
Most real systems combine several patterns. Don’t be a purist.
Building Blocks: Memory, Tools, and Orchestration
Let’s get into the nuts and bolts. If you’re going to build a multiagent system, you’ll spend most of your time on three things: memory, tools, and orchestration.
Memory: The Agent’s Brain
Agents without memory are goldfish. They forget everything between turns. There are three layers to think about:
Working memory is the current conversation context. It’s ephemeral, lives in the prompt, and is bounded by your context window.
Episodic memory is a log of past interactions — “last Tuesday, the user asked about X and we solved it like Y.” Typically stored in a vector database with semantic retrieval.
Semantic memory is structured knowledge — facts, schemas, relationships. Often a knowledge graph or relational database.
Procedural memory is learned behavior — successful prompt patterns, tool-use strategies, workflow templates. This is the newest frontier and arguably the most valuable.
Practical tip: Start with working + episodic memory. Add semantic and procedural memory only when you’ve measured a real need. Premature optimization here burns time.
Tools: Giving Agents Hands
An agent without tools is just a fancy autocomplete. Tools are what let agents act.
Common tool categories:
- Code execution: Sandboxed Python, shell, SQL.
- Search: Web, codebase, documentation.
- File I/O: Read, write, edit files in a controlled workspace.
- APIs: Anything from GitHub to Jira to your internal services.
- Other agents: Yes, agents can call agents. This is how hierarchies form.
The golden rule of tool design: make tools self-describing. Agents pick tools based on their descriptions. A poorly documented tool is an unusable tool. Write tool descriptions like you’re explaining to a smart new hire on their first day.
Orchestration: The Conductor
Orchestration is where most teams get stuck. You have agents, you have tools, you have memory — now how do you make them dance?
Three mainstream approaches:
Code-first orchestration. You write Python (or TypeScript) that explicitly calls agents in sequence. Frameworks like LangGraph and Auto Gen lean this way. Maximum control, maximum effort.
Declarative orchestration. You define workflows in YAML or JSON — “Agent A does X, then hands off to Agent B.” Tools like CrewAI and Dify offer this. Faster to iterate, less flexible.
Autonomous orchestration. You give a meta-agent the ability to decide which sub-agent to call next. Maximum flexibility, minimum predictability. Use with caution and heavy logging.
My honest recommendation: start code-first. You’ll learn more about your problem in a week of writing orchestration code than in a month of configuring a framework. Once you understand the patterns, you can abstract them.
Real-World Applications and Case Studies
Enough theory. Where is this actually working?
Software Engineering
The most visible win. Companies like Devin (Cognition), Factory, and various internal teams at big tech are shipping multiagent coding systems. The typical setup:
- A planner agent breaks a GitHub issue into tasks.
- Coder agents implement each task in isolated branches.
- Reviewer agents run static analysis and suggest fixes.
- A test agent runs the suite and reports back.
- A coordinator agent merges and opens the PR.
These systems aren’t replacing engineers. They’re handling the tedious middle 60% of a ticket — the boilerplate, the tests, the docs — so engineers can focus on architecture and judgment calls.
Customer Support
Multiagent support systems are quietly handling millions of conversations. A triage agent classifies the request, a knowledge agent retrieves the right docs, a resolution agent drafts the reply, and a compliance agent checks for policy violations. Escalation to humans happens when confidence is low.
The ROI here is measurable and significant. Some teams report 40–60% deflection rates on tier-1 tickets.
Research and Analysis
Pharma, finance, and consulting firms are using multiagent systems to synthesize large bodies of literature. One agent pulls papers, another extracts key findings, a third cross-references claims, a fourth writes the summary. What used to take a junior analyst a week now takes an afternoon — with human review at the end.
Data Engineering
ETL pipelines are getting agent-powered. An agent profiles incoming data, another writes transformation code, a third validates the output, a fourth monitors for drift. The human data engineer becomes a supervisor rather than a pipeline mechanic.
Internal Knowledge Work
Every company has the same problem: institutional knowledge is scattered across Slack, Confluence, Google Drive, email, and people’s heads. Multiagent systems are being deployed as “organizational memory” — agents that can answer questions like “What was the decision we made about pricing in Q3 last year, and who was involved?”
These are early days, but the trajectory is clear. Any knowledge work that involves gathering, synthesizing, and producing is fair game.
A Practical Guide: Building Your First Multiagent System
Let’s get concrete. If you want to build a multiagent system this weekend, here’s a path that works.
Step 1: Start With a Single Agent That Sucks
Seriously. Build one agent that tries to do everything. Watch it fail. Note where it fails. Those failure modes tell you where to split.
Maybe it’s great at research but bad at writing. Split. Maybe it writes well but hallucinates facts. Add a verifier. Maybe it loses track of long conversations. Add memory.
Don’t design your agent topology in a vacuum. Let the failures teach you.
Step 2: Define Clear Roles and Interfaces
Each agent should have:
- A name and a persona (yes, personas matter — they shape behavior).
- A system prompt that defines its role, constraints, and output format.
- A tool set — the minimum tools it needs to do its job.
- A handoff protocol — how it receives input and returns output.
Write these down. If you can’t describe an agent in three sentences, it’s doing too much.
Step 3: Pick Your Stack
For a weekend project, keep it simple:
- Framework: LangGraph, CrewAI, or OpenAI’s Agents SDK. All three are solid. LangGraph gives the most control; CrewAI is the fastest to prototype.
- Model: Use a capable model for orchestration (Claude Sonnet, GPT-4.1, Gemini 2.5) and cheaper models for worker agents where appropriate.
- Memory: Start with in-memory. Add a vector store (Chroma, Qdrant, or pgvector) only when you need persistence.
- Observability: LangSmith, Arize Phoenix, or Braintrust. You will need to debug. Don’t skip this.
Step 4: Build the Orchestration
Start with a simple sequential pipeline. Get it working end-to-end. Then iterate:
- Add branching where you need conditional logic.
- Add loops where agents need to refine their output.
- Add parallelism where tasks are independent.
Resist the urge to make it autonomous too early. Deterministic orchestration is boring but reliable. Autonomous orchestration is exciting but fragile. Earn your autonomy.
Step 5: Evaluate Ruthlessly
This is where most teams fail. They build a cool demo and call it a day. Don’t.
Build an eval suite:
- Unit evals: Does each agent do its specific job correctly?
- Integration evals: Does the handoff between agents preserve information?
- End-to-end evals: Does the system solve real problems from your domain?
- Regression evals: When you change a prompt, does anything break?
Run these evals on every change. Treat them like unit tests.
Step 6: Ship, Measure, Iterate
Put it in front of real users. Measure:
- Task completion rate
- Latency and cost per task
- User satisfaction
- Failure modes and frequency
Then iterate. Multiagent systems are never “done.” They’re living systems that evolve with your needs.
Common Pitfalls (Learn From My Mistakes)
A few things I’ve seen go wrong, repeatedly:
Over-engineering the topology. Three well-designed agents beat fifteen poorly designed ones. Start small.
Ignoring prompt drift. Agents that work today may fail next month after a model update. Pin your models. Version your prompts.
Under-investing in evals. If you can’t measure it, you can’t improve it. Build evals before you need them.
Skipping observability. When something breaks at 2 a.m., you’ll wish you had logs. Trace every agent turn.
Treating agents like magic. They’re not. They’re probabilistic systems that need guardrails, validation, and human oversight. Design accordingly.
The Road Ahead
Where is this all going? A few bets:
Agent-to-agent protocols will standardize. MCP (Model Context Protocol) and A2A (Agent-to-Agent) are early signals. Expect convergence.
Specialized agent models will emerge. Instead of using general LLMs for everything, we’ll see models fine-tuned for specific agent roles — code review, research, planning.
Agent marketplaces will appear. You’ll be able to plug in pre-built agents for common tasks, like npm packages for cognition.
Regulation will catch up. As agents take on more consequential actions, questions of liability, auditability, and control will get louder.
The teams that figure this out early — not by chasing hype, but by building thoughtfully — will have a structural advantage. Not because they have smarter models, but because they’ve learned to think in systems.
Multiagent AI systems aren’t a replacement for good engineering. They’re an amplifier. AI-native development isn’t about letting machines run wild — it’s about designing workflows where humans and agents each do what they’re best at.
If you take one thing from this post, let it be this: start small, measure everything, and let the failures guide your design. The teams winning in this space aren’t the ones with the biggest models. They’re the ones with the clearest thinking.
Your move. Pick a problem you’ve been meaning to automate. Build a single agent. Watch it fail. Split it. Iterate. Ship.
The future of software isn’t written by solo coders or solo models. It’s written by teams — human and artificial — learning to think together.
What’s the first multiagent system you’re going to build? Drop it in the comments — I’d love to hear what you’re working on.
FAQS
- What exactly is a multiagent AI system?
A multiagent AI system is a collection of autonomous AI entities, each with specific roles and tools, that collaborate to solve complex tasks that a single model would struggle with.
- How is multiagent AI different from using ChatGPT or Claude directly?
Single-model chat is one agent doing everything. Multiagent systems split work across specialized agents with memory, tools, and coordination — like a team vs. a solo worker.
- Do I need to know machine learning to build multiagent systems?
No. Most modern frameworks (LangGraph, CrewAI, OpenAI Agents SDK) are Python/TypeScript libraries. You need strong software engineering skills, not ML expertise.
- What’s the best framework for beginners?
CrewAI is the most beginner-friendly. LangGraph offers more control. OpenAI’s Agents SDK is great if you’re already in the OpenAI ecosystem.
- Are multiagent systems expensive to run?
They can be. Each agent turn costs tokens. Good design — using smaller models for worker agents, caching, and limiting loops — keeps costs manageable.
- How do agents communicate with each other?
Through structured messages, shared memory (blackboards), or direct function calls. The orchestration layer defines the protocol.
- What is AI-native development?
It’s building software with the assumption that AI agents are first-class participants in the development process, not just assistants.
- Will multiagent systems replace software engineers?
No. They’ll change the job. Engineers will spend less time on boilerplate and more time on architecture, judgment, and agent orchestration.
- How do I prevent agents from hallucinating?
Use verifier agents, ground agents in tools (search, code execution), add retrieval-augmented generation, and build eval suites to catch drift.
- What’s the difference between LangGraph and CrewAI?
LangGraph is graph-based and code-first — maximum control. CrewAI is role-based and declarative — faster to prototype but less flexible.
- Can agents use external APIs?
Yes. Tools are how agents interact with the world. You can give agents access to any API you can call from code.
- How do I debug a multiagent system?
Use observability tools like LangSmith or Arize Phoenix. Trace every agent turn, log inputs and outputs, and build replay capabilities.
- What models should I use for agents?
Use capable models (Claude Sonnet, GPT-4.1, Gemini 2.5) for orchestration and reasoning. Use cheaper, faster models for simple worker tasks.
- How do I handle agent memory?
Three layers: working memory (current context), episodic memory (vector store of past interactions), and semantic memory (structured knowledge). Start with working memory.
- What is MCP (Model Context Protocol)?
MCP is an emerging standard for how agents connect to tools and data sources. Think of it as USB-C for AI agents.
- What is A2A (Agent-to-Agent) protocol?
A2A is Google’s protocol for agent-to-agent communication. It complements MCP by handling inter-agent coordination.
- Can multiagent systems work offline?
Yes, if you use local models (Llama, Qwen, Mistral) and local tools. Latency and quality will vary vs. cloud models.
- How do I evaluate a multiagent system?
Build unit evals (per agent), integration evals (handoffs), end-to-end evals (full task), and regression evals (after changes). Treat them like tests.
- What are common failure modes?
Infinite loops, error propagation, context loss at handoffs, hallucination amplification, and cost blowups from runaway agents.
- How do I keep costs down?
Use smaller models where possible, cache results, limit loop iterations, and short-circuit when confidence is high.
- Can agents write and deploy code?
Yes, but with guardrails. Sandboxed execution, human review for production deploys, and automated tests are non-negotiable.
- What’s a swarm pattern?
A decentralized pattern where agents hand off to each other peer-to-peer based on context, with no central supervisor.
- What’s a hierarchical pattern?
A supervisor agent delegates to worker agents, reviews their output, and synthesizes a final answer.
- How do I handle conflicting agent outputs?
Use a judge agent, implement voting, or escalate to a human. Debate patterns are specifically designed for this.
- Are multiagent systems secure?
They can be, but you need to think about tool permissions, data access, prompt injection, and audit trails. Security is a first-class concern.
- What industries benefit most from multiagent AI?
Software engineering, customer support, research, finance, legal, healthcare, and any knowledge-intensive field.
- How long does it take to build a multiagent system?
A simple prototype: a weekend. A production system: weeks to months, depending on complexity and eval rigor.
- Do I need a PhD to understand this stuff?
No. Strong software engineering fundamentals and curiosity are enough. The field moves fast, but the concepts are accessible.
- What’s the future of multiagent AI?
Standardized protocols, specialized agent models, agent marketplaces, and tighter human-agent collaboration. The trajectory is toward more capable, more composable systems.
- Where should I start learning?
Build something small. Pick a real problem, use CrewAI or LangGraph, and iterate. The best learning happens when you’re shipping.
Disclaimer: The content on this blog is for informational purposes only. The author’s opinions are personal and not endorsed. Efforts are made to provide accurate information, but completeness, accuracy, or reliability are not guaranteed. The author is not liable for any loss or damage resulting from the use of this blog. It is recommended to use the information on this blog at your own discretion.